The control plane for AI agents
AI agents you can trust to run the business.
Every agent in your company, on the right engine. Tight control where a wrong answer costs money. Speed everywhere else.
The problem
Your company is quietly filling up with agents. Nobody is in charge of them.
Sales builds one. Ops builds another. Support builds a third. Each one architected alone, with no shared expertise, no evaluation, and no way to see them all in one place.
- 01Overpowered agents doing simple jobs, burning tokens
- 02Underspecified agents doing critical jobs, failing silently
- 03Spend climbing across providers and models, reliability unchecked, no one who owns the whole picture
112 agents.
Zero shared architecture.
You have seen this movie. It was called microservices sprawl.
The companies that survived it built a platform layer.
Why agents fail in production
Production has rules. Demos don't.
Agents re-do work
30K to 80K
tokens per query
A standard agent re-reads the same documents on every step. Every query, all over again.
Errors compound
95% → 60%
per step → after ten steps
Each step adds a chance to be silently wrong. More steps means less trust, not more.
Nobody built for scale
0
evals, traces, baselines
Each agent was a side project. There is nothing to measure it against and no one watching.
Every step re-pays for every step before it.
A standard agent re-sends the full transcript on every call. Step 1 runs. Step 2 re-sends step 1. Step 3 re-sends steps 1 and 2. The transcript itself becomes the bill. Your cost grows with the square of the steps, not the size of the job.
Six steps of work.
You pay for 21.
1.0xthe tokens, and the bill, for the same job.
The usual way to cut agent spend is to cut corners.
The easy savings
- 01Switch to a cheaper model
- 02Drop verification steps
- 03Shorten the context window
The hidden cost
Every one quietly raises your error rate. Fine for drafting emails. On contracts, compliance, money, and customers, one silently wrong answer costs more than every token you saved.
That is a bad trade. There is a better one.
The framework
Match the engine to the risk.
We sort every workflow by two questions: how much does a wrong answer cost, and how tightly defined is the task. Only one quadrant needs a deterministic engine. The rest stays fast, open-ended, and flexible, which is the point of an agent.
High stakes · Open ended
Real consequences but the task is fuzzy.
→ tighten the spec first
High stakes · Well defined
Document review, compliance checks, financial extraction.
→ OpenSymbolic. Same answer every time.
Low stakes · Open ended
Drafting, brainstorming, summaries.
→ fast, flexible agents
Low stakes · Well defined
Routine structured tasks.
→ standard agents, lightly checked
What we install
We are the platform layer for your agents.
Microservices sprawl got solved by platform engineering: one team, shared tooling, a standard way to build, deploy, and observe. Agents need the same thing. That is what we install. You stop overpaying on the easy stuff and stop gambling on the stuff that matters.
01
Map
We inventory every agent workflow and sort it onto the risk grid.
02
Deploy
High stakes, defined work moves onto OpenSymbolic, our open source deterministic engine. Everything else stays on the tools you already use, checked and observed.
03
Observe
One place to see every workflow, its cost, its error rate, and its blast radius.
The pilot produces these numbers. The product makes them continuous.
The engine
Send logic, not data.
Plan
The model writes an execution plan once.
Execute
Python runs it: retrieval, filtering, extraction. The model never touches raw data.
Reason
The model sees only the final selected evidence.
Documents never get re-read. On recurring, high volume, document heavy workflows, that is 86% fewer tokens. And because code is deterministic, failures are bugs you fix once, not prompts you re-tune forever, on every model release.
How it works, in full →Independent eval
Zero errors. Verified by someone other than us.
BoonAI ran OpenSymbolic against their production RAG pipeline on 104 real queries over their own document corpus. Recurring, high-volume, document-heavy work.
Same or better answers. Their data, their judge, not ours.
~Human
Backed by a theorem prover, not a guess.
7 of 11 models
hit 100% on TravelPlanner. Swap models with one config change.
The industry just agreed with us.
The move
In the last year, Nvidia and AWS open sourced agent frameworks that blend deterministic code with LLM planning, and instrumentation layers to watch them. The giants have concluded what we built OpenSymbolic on: raw model loops cannot be trusted with high stakes work.
The gap
What they ship is software. What nobody ships is the map: which of your workflows belong on which engine, and the discipline to move them. That is us.
Our bet
OpenSymbolic is MIT licensed. The architecture is open on purpose. The value is in deploying it against the workflows where being wrong costs you money.
The pilot
Pick one workflow. We prove it on your data in two weeks.
01
Map your risk grid
We sort your agent workflows by stakes and definition.
02
Deploy on one workflow
High value, high stakes, well defined.
03
Measure head to head
Cost, error rate, and latency against what you run today.
All we need: a point of contact engineer and a representative set of queries. No system access. A layer, not a replacement. If the number does not convince you, keep the learnings and the MIT code and walk away.
We work with a small number of founding partners on paid pilots.
Book a pilotWho you work with
Your platform team.
Just the two of us, and that's the point. You work directly with the people who built it. We met inside Dropbox's incubator, building enterprise AI products, and kept hitting the same wall: models that demoed brilliantly but couldn't be trusted at scale. OpenSymbolic is the fix, at the root.
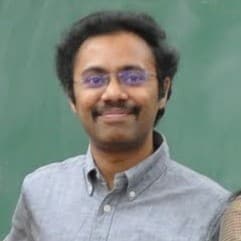
Rajkumar Janakiraman
Tech
14 years engineering at Microsoft before co-founding the internal incubator at Dropbox that became Dropbox Dash, one of the first enterprise AI products to ship at scale on GPT-3.
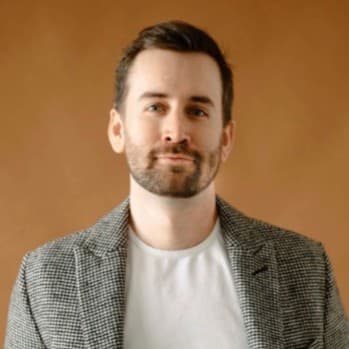
Chase Croft
Product / GTM
Built seven products from zero to one, twice as a founder and inside Dropbox's and Walmart's incubators. Turns OpenSymbolic's technical edge into workflows enterprises can adopt and trust.
The winners of the agent era will not be the companies with the most agents. They will be the ones who can trust theirs.
We make that trust your default. And it happens to cost a fraction of what you spend today.
Let's pick the first workflow